If you’ve noticed your favorite illustrator suddenly vanish from Instagram, or that one parent friend scrubbing every photo of their kid from Facebook, you’re not imagining it. In the last few years, people have removed content from the web over concerns about generative AI.
That can look like a lot of different things: artists pulling their portfolios offline after discovering AI models spitting out paintings in their own style, parents deleting family photos over fears their kids’ faces could end up in a deepfake, or businesses blocking AI crawlers from accessing their website entirely.
DreamHost sees this firsthand: across the websites DreamHost hosts, site owners are actively blocking some or all AI web crawlers.
In other words, there’s a real and measurable concern about how AI tools access, understand, and ingest the content we all put online.
It’s not that these worries are new.
The internet has always been a messy place for consent, privacy, and ownership. What’s changed is that AI has forced everyone — creators, families, and small business owners alike — to finally confront just how little control they have over what they put online.
At DreamHost, we’ve always believed the open web thrives when creators control what they share and how it’s used. The web works best when ownership sits with the people who built it — not just the platforms that profit from it.
And that brings us to the heart of the matter. The real question is who gets to decide, rather than what AI can do.
Should you block AI crawlers from your website?
Should you block AI crawlers? It depends on what you value more: visibility or control. Blocking AI training crawlers like GPTBot and Google-Extended tells compliant bots to leave your content out of model training, without removing you from traditional search results — though compliance is voluntary, and rogue scrapers can ignore the rules. Staying open maximizes your reach in AI answers and summaries. Neither choice is wrong. What matters is that you make it yourself, deliberately.
AI isn’t the villain here. The real threat is “platform paternalism,” or companies that make “ethical” choices on behalf of everyone else. For example, in July 2025, Cloudflare (one of the web’s largest network providers) began blocking AI crawlers by default for new customers — its 2024 blocking tools had been opt-in — positioning the move as protection for creators. The result: for millions of new sites, the default answer to AI crawlers was decided by the provider, not the owner. Reversible, yes, but set without their input.
It’s like your landlord locking your door for your safety, but without giving you the right keys. So what started as a convenience quickly turns into a loss of agency. When gatekeepers decide what “protection” looks like, individual autonomy shrinks.
The open web was built on permissionless innovation, meaning anyone could create, share, and iterate without asking for approval. Intermediaries deciding which bots or tools can access content may rewind that freedom by decades.
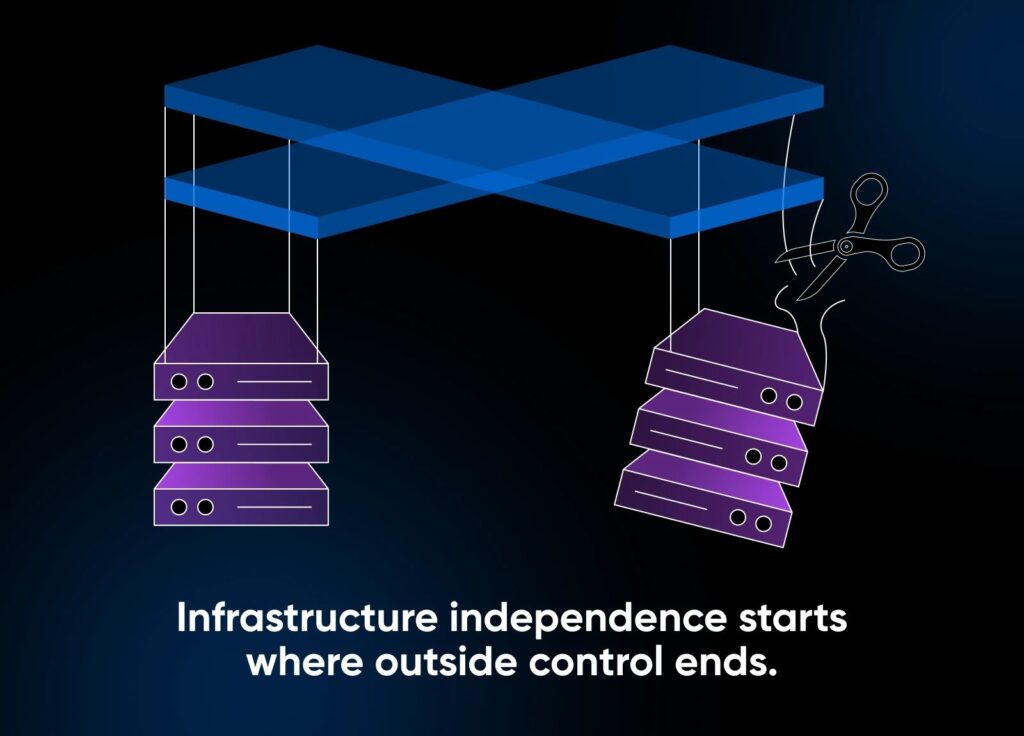
That’s why DreamHost advocates for infrastructure independence: when you host your own content, no one can rewrite your rules. Owning your stack means owning your policies, whether you welcome AI crawlers or shut them out entirely. The ethics don’t come from code; they come from choice.
“AI needs your data” and other myths
So what keeps creators from reclaiming control? Oftentimes, misinformation, like these pervasive myths surrounding AI. These myths are popular because AI use has proliferated around the internet and the tools we use every day.
Myth #1: “AI needs your data to progress”
No one owes for-profit AI companies their work. Licensed and consent-based models exist; for example, Adobe Firefly trains on licensed content with permission and public domain works without copyright. The future of AI doesn’t need to depend on stealing. It can depend on consent instead.
Myth #2: “If you opt out, you’ll disappear”
Opting out may limit your appearance in AI-generated summaries or search snippets, but it won’t erase you from the web. Think of it like opting out of Google in 2005. You’d lose reach rather than relevance, especially if your audience still seeks you directly.
While it may not be practical for anyone who depends on reach to grow their audience or customer base (though we still don’t have great data on how much organic traffic actually comes from GEO), for some creators, visibility isn’t worth involuntary use. The key is that they get to decide.
Myth #3: “AI scraping is just how the internet works”
Indexing for discovery and appropriating for training aren’t the same thing.
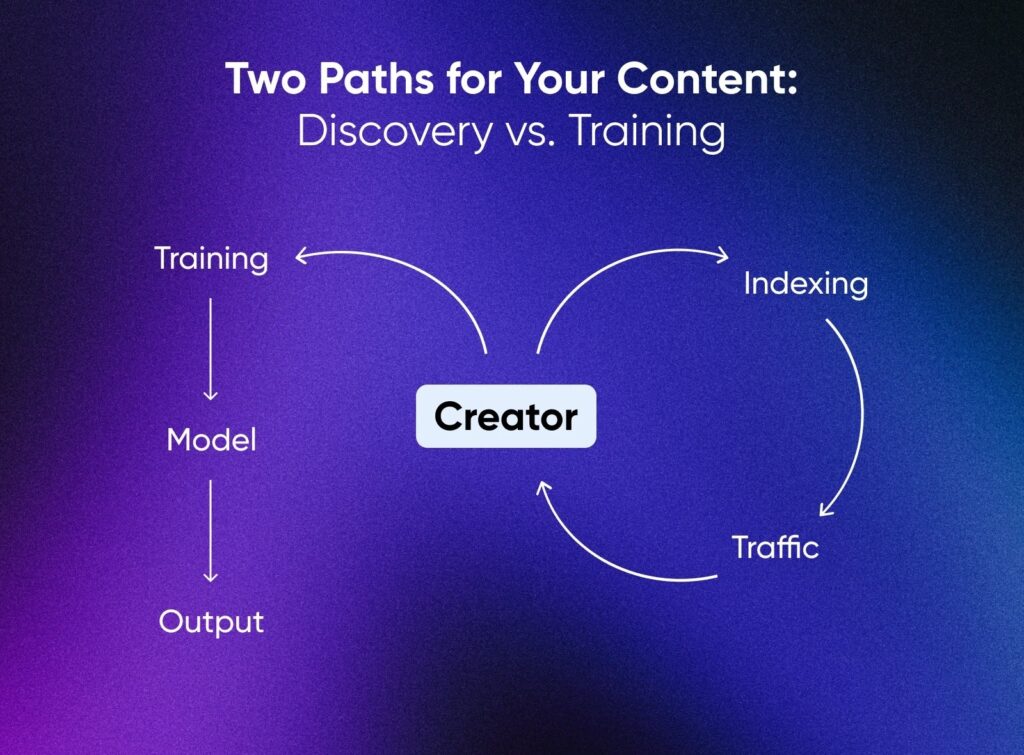
Indexing drives people to your site. Training replaces you with a statistical copy. Publishers like the Associated Press and Axel Springer are proving there’s a middle ground: both have signed content-licensing deals with OpenAI, and Axel Springer’s deal was reportedly worth tens of millions of euros.
Even good intentions can backfire. The bottom line is that balanced ethics require informed consent.
Opting out vs. staying open: The real trade-offs
Every AI stance — from full openness to total opt-out — comes with real opportunity costs. Deciding where you stand depends on what you value most, from visibility to control to sustainability to autonomy.
DreamHost’s internal data shows that about 71.5% of traffic across DreamHost-hosted websites since January 2025 comes from bots, not humans (industry-wide, Imperva’s 2025 Bad Bot Report puts it at 51%). That means most of the requests hitting your site are automated: some beneficial (like search indexing or uptime monitoring), others less so. Managing which crawlers you allow and which you block is ethical sustainability in action.
Below are four common approaches creators take to AI access and training and how each impacts different open web factors, so you can visualize the trade-offs before locking in your stance.
| Fully Open | Selective Licensing | Block AI Training | Fully Opted Out of AI | |
| Visibility and Reach | Highest; AI summaries and search engines can surface your work everywhere. | Moderate; exposure limited to partners who license content. | Low; excluded from AI results but still appears in traditional search. | Lowest; you’ve asked both AI and many discovery crawlers to stay out. |
| Control and Consent | Minimal; platforms decide for you. | High; governed by explicit licensing terms. | Strong; you define permissions via robots.txt and HTTP headers. | Strongest; your policy prohibits all automated access, though enforcement still depends on crawlers complying. |
| Attribution | Low; most AI models don’t cite sources. | High; attribution and royalties built into contracts. | Medium; compliant crawlers may still credit you. | Lowest; compliant crawlers won’t reference your content, though rogue crawlers may still access it. |
| Risk of Misuse or Copying | High; style or text may be replicated freely. | Moderate; legal recourse via license terms. | Low; compliant bots deterred, rogue bots still possible. | Very low; minimal surface area to scrape. |
Each path has merit. Marketers and small business owners often depend on visibility to grow their audiences, while illustrators, journalists, and educators may prioritize ownership and consent above all else. The web thrives on diversity, and ethical AI participation should reflect that diversity of goals.
Rather than a universal right answer, there are only informed trade-offs that align with your principles and how you earn a living online. Since there is no one-size-fits-all approach, you should form your stance consciously and back it up with action. Whatever path you choose, make it intentional.
How to decide your AI stance
Ethics only matter when they’re practiced. Here’s how to turn theory into action and define how AI interacts with your work.
Step 1: Clarify your goals
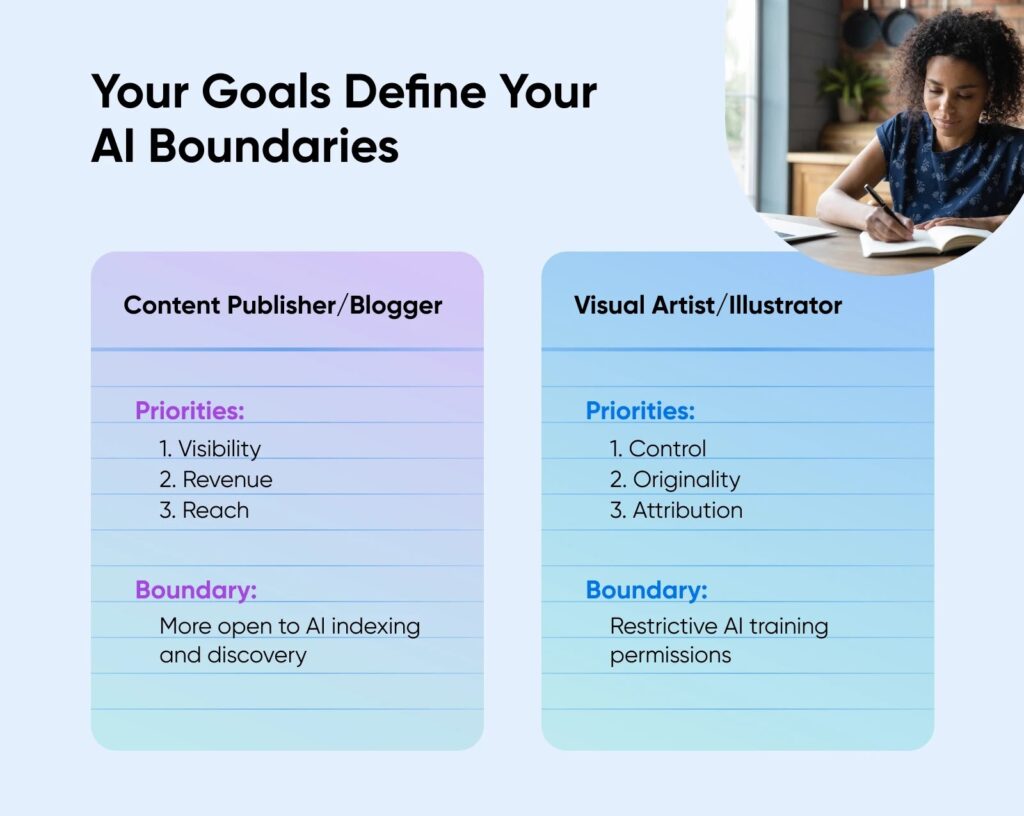
Start by ranking what matters most to you: visibility, revenue, sustainability, control.
A small business chasing reach may tolerate broader AI use, while an illustrator guarding originality may not. Different goals = different boundaries.
Step 2: Audit your digital footprint
List where your content lives: WordPress sites, GitHub repos, social media, cloud storage. Platforms apply their own AI policies, so hosting independence gives you the freedom to set rules per site instead of accepting blanket defaults set by the platforms you use (without your input).
Step 3: How to block AI crawlers with robots.txt
To block AI crawlers, add a disallow rule for each crawler’s user agent to your robots.txt file. Here’s a starter block covering the major AI crawlers:
User-agent: GPTBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Applebot-Extended
Disallow: /

User-agent: PerplexityBot
Disallow: /
Trim the list to match your stance (Google-Extended, for example, controls AI training only, not your search rankings). You can also add headers like X-Robots-Tag: noai, noimageai, but treat robots.txt as your primary control: those tags are non-standard signals, and per Originality.ai’s adoption tracking, most major AI crawlers haven’t formally committed to honoring them. And remember, compliance is voluntary either way. These signals state your wishes, but they don’t enforce them.
Step 4: Publish a transparent AI policy
Create a simple page stating your position. For example:
| “AI systems may not use this content for training or replication.” |
Transparency builds trust with clients and sets clear boundaries for future use.
Step 5: Monitor and adapt
Use server logs or analytics to track your bot mix. Review quarterly and update your rules as new crawlers emerge.
The only AI ethics that matter are your own
People have ethics, even if AI does not. What matters isn’t whether you blocked every crawler or embraced every tool; it’s that you made those choices on purpose.
The web was built on freedom to share, remix, experiment, and build without permission. True digital ethics protects that same spirit of self-determination.
You’ve moved from fear to control, from uncertainty to ownership. At DreamHost, we believe owning your digital presence is both smart business and a way to keep your ethics intact in a world run by algorithms.
The open web remains yours, if you choose to own it.
FAQs about blocking AI crawlers
Does robots.txt actually stop AI scraping?
Not by itself. robots.txt is a voluntary protocol: compliant crawlers like GPTBot and Google-Extended honor it, but others ignore it — content licensing platform Tollbit counted over 26 million scrapes that ignored the protocol in March 2025 alone. For real enforcement, add server- or network-level blocking.
Will blocking AI crawlers hurt my Google rankings?
No. Google-Extended only controls whether your content trains Google’s AI models. Search indexing is handled by Googlebot, a separate crawler, so blocking Google-Extended leaves your rankings and traditional search visibility untouched.
Which AI crawlers should I block?
If your goal is keeping your content out of model training, start with GPTBot (OpenAI), Google-Extended (Google), ClaudeBot (Anthropic), CCBot (Common Crawl), and Applebot-Extended (Apple). Leave retrieval and indexing bots alone if you still want AI tools to cite you.
Can I license my content to AI companies instead?
Yes. The Associated Press and Axel Springer have signed content-licensing deals with OpenAI (Axel Springer’s was reportedly worth tens of millions of euros), and pay-per-crawl marketplaces are emerging that let smaller sites charge AI companies for access. Licensing trades open access for paid, permissioned use.